
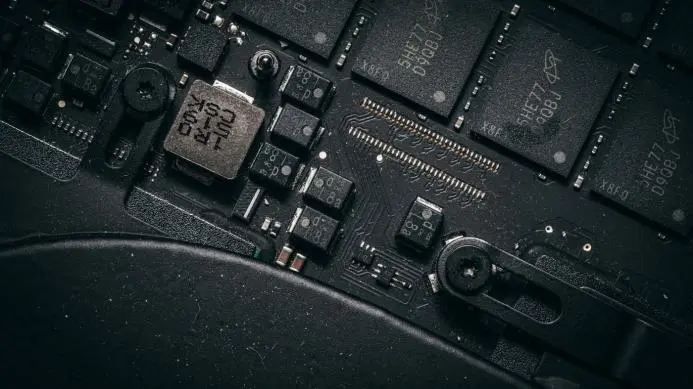
Local AI model deployment often stalls because of insufficient video memory, a bottleneck that directly impacts who can run these tools on their own hardware. The NVIDIA RTX 5080 addresses this constraint by offering 16GB of GDDR7 memory, which allows users to run large language models that previously required enterprise-grade hardware. This shift matters because it lowers the barrier for developers and enthusiasts to test and deploy models like Qwen3.8-27B without relying on expensive cloud services.
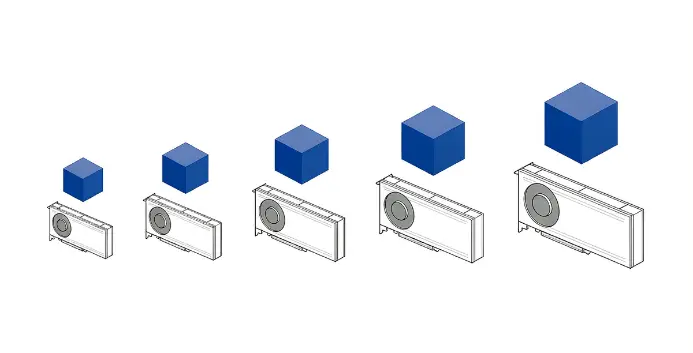
16GB GDDR7 memory supports local 27B parameter model deployment
The graphics card relies on its 16GB GDDR7 VRAM to handle the memory demands of quantized AI models. NVIDIA specifies that the RTX 5080 delivers 1801 AI TOPS, a metric that indicates its processing power for artificial intelligence workloads. This hardware configuration targets users who need to balance performance with a manageable memory footprint for local inference tasks.
- VRAM: 16GB GDDR7
- AI TOPS: 1801
- Model Example: Qwen3.8-27B_Q4
Running a 27-billion parameter model with 4-bit quantization requires careful calculation of memory usage. The total VRAM needed includes the model weights, plus approximately 5% overhead for the system framework, and about 2GB for the KV cache. For the Qwen3.8-27B_Q4 model, this formula results in a requirement of roughly 16.175GB of video memory.
The RTX 5080 sits just below the 16.175GB threshold required for the Qwen3.8-27B_Q4 model. Despite this slight gap, the card can run the model smoothly when users adjust quantization settings and context lengths appropriately. This flexibility means the hardware remains viable for this specific workload, provided users manage their context windows carefully.
We looked at NVIDIA Tesla P100 Gains 88% Speed in our earlier Nvidia coverage. The RTX 5080 represents a consumer-focused alternative to those older enterprise solutions for running large models locally.
The RTX 5080 provides a practical path for running 27B parameter models locally, given its 16GB GDDR7 memory and 1801 AI TOPS capability. Users can achieve smooth performance by optimizing quantization and context settings to fit within the available VRAM.

Discussion
0 comments
Log in to join the thread with a thoughtful take, question, or correction.