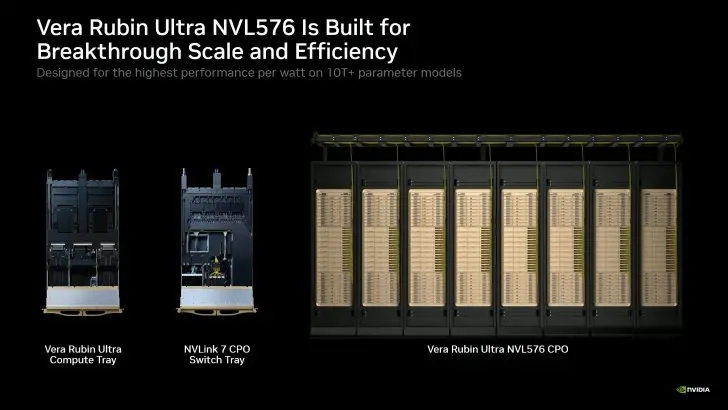
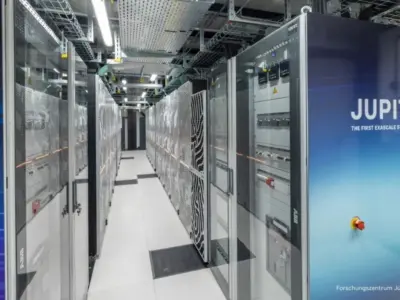
Nvidia is coming up with a giant rack datacenter called Rubin Ultra NVL576. It is a revolutionary approach to AI infrastructure. It's significant as it allows people to pool 576 GPUs into a single logical GPU.
Nvidia pools 576 GPUs into a single logical unit with 14x performance gains
So, it will help with large language model scaling. For the people looking to deploy massive AI clusters, this architecture will help them reduce the complexity of managing thousands of separate GPU cards.
Specifications
- Architecture: Rubin Ultra
- GPU Count per Rack: 576
- GPU Memory: 1TB HBM4e per GPU
- Rack Memory Bandwidth: 4.6 PB/s
- Inference Performance (FP4): 15 Exaflops
The architecture of Rubin Ultra with Vera CPUs is at the center of this setup. Nvidia has connected 576 GPUs together with next-gen Co-Packaged Optics and NVLink technology. So, essentially they have made a giant GPU that can process data for the whole rack as a single unit.
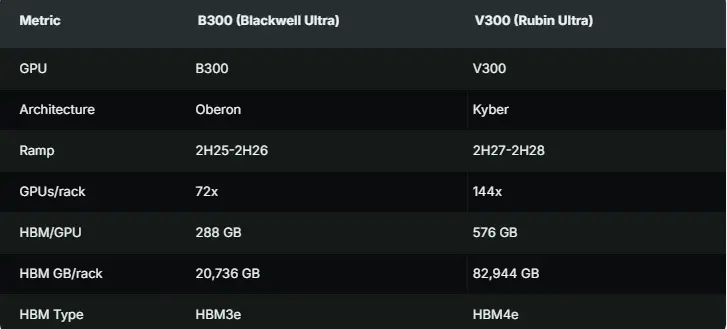
There is 1TB HBM4e memory on every GPU in the rack. So, it gives a total rack bandwidth of 4.6 PB/s. It is optimized for 15 Exaflops of FP4 inference and 5 Exaflops of FP8 training. This is a 14x performance increase in comparison to the existing Blackwell GB300 NVL72 solution.
At GTC Berlin, Jensen Huang has confirmed that the CPO racks have started mass production. Nvidia claims this setup is the most energy-efficient in the world. Globally, they are going to release Rubin Ultra NVL576 next year.
It is the successor to the Blackwell GB300 NVL72. The Rubin Ultra architecture and HBM4e memory adoption is a significant step forward in terms of hardware density. How well it will work in practice when deployed, will be seen next year when it will be released.
Discussion
0 comments
Log in to join the thread with a thoughtful take, question, or correction.