The update was made to DeepSeek V4.1 Flash to run in higher precision on a lawyer’s eight-GPU homelab server. This is an important point for anyone interested in building low-cost private AI systems. The upgrade leads to better next-token fidelity, although code generation speed is affected. This way people can still run the model on older Nvidia GPUs with minor fidelity losses.
Lawyer upgrades 8x V100 server to run DeepSeek V4.1 Flash with 1TB RAM
Nick Mermiges uses his server to secure legal documents and experiment with large language models. He changed around 80% of DeepSeek V4.1 Flash model experts from 2-bit NVFP4 to 4-bit precision. The other 20% are still 2-bit for memory efficiency. This combination is what enables the model (556GB weights) to fit on consumer GPU cards.
System Specifications
- GPU Configuration: 8x Nvidia Tesla V100 (32GB each)
- System RAM: 1TB (8x 128GB modules)
- Additional GPU: Nvidia RTX 3090
- Model Precision: 80% at 4-bit NVFP4, 20% at 2-bit
- Model Weights Size: ~556GB
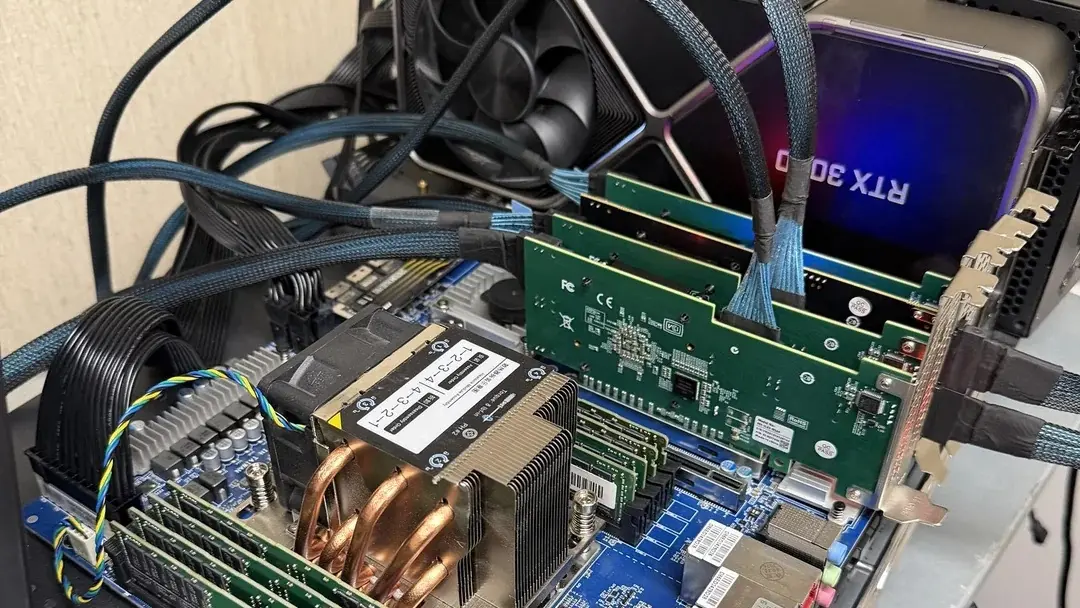
Mermiges’ system features eight Nvidia Tesla V100 GPUs with 32GB RAM each. System RAM was increased to 1TB (up from 256GB) to accommodate the bigger model. An Nvidia RTX 3090 was added for draft model offloading.
The system was previously crashing due to a bad power supply. The power supply was replaced to solve the stability problem.
The upgrade results in 95.1% fidelity on same-next tokens. This is compared to Nvidia reference implementation. Code generation speed goes down 3%-30% depending on the prompt length.
With this setting two requests can be served at the same time. Combined output is 159.0 tokens per second. Mermiges states that the documents do not leave the office during these experiments.
In our previous article about the DeepSeek V4.1 Flash update some of the same trade-offs and stability points were discussed. The current build demonstrates that people can adjust the precision levels to match their GPU capabilities. It’s also a great example that older V100 GPUs can be used with modern AI models when tweaked correctly.
That 1TB RAM upgrade is the real story here. The V100s have enough VRAM for the weights, but the context window needs that system memory to not crash.