
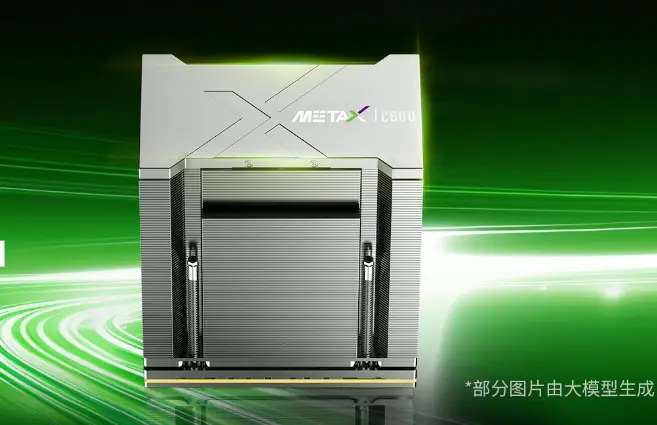
MetaX has secured official support for its Xi Cloud C Series GPU within the CNCF-hosted llm-d project, marking the first time a domestic Chinese GPU has entered this international open-source ecosystem. This integration matters because llm-d provides cloud-native distributed inference capabilities built on vLLM and Kubernetes, giving Chinese hardware vendors a validated path into global AI infrastructure standards. Buyers and developers monitoring domestic GPU progress can now track this card as a viable option for containerized LLM deployment.
First domestic GPU to join CNCF llm-d with optimized deployment paths
The adaptation effort was completed in collaboration with Dynamia AI, positioning the Xi Cloud C Series as a software-ready component for modern inference workloads. llm-d serves as a distributed inference framework that simplifies the deployment of large language models across Kubernetes clusters. By achieving compatibility, MetaX demonstrates that its hardware can interface with established open-source tools without requiring custom, isolated software stacks.
- llm-d Compatibility: First domestic GPU added to llm-d official accelerator list
- Qwen3-14B Single Card Throughput: 5773 tokens/s
- DeepSeek-R1-Distill-Llama-70B 8-Card Throughput: 5468 tokens/s
- Deployment Paths: Optimized baseline single card, optimized baseline eight card, Prefill/Decode separation
Performance benchmarks from the collaboration highlight specific throughput metrics for common model configurations. The GPU achieves a peak Prefill throughput of 5773 tokens per second when running the Qwen3-14B model on a single card with tensor parallelism set to one. In a multi-card setup, the system processes the DeepSeek-R1-Distill-Llama-70B model at 5468 tokens per second using eight cards with tensor parallelism set to eight. These figures provide concrete data points for estimating capacity in single-node and cluster environments.
MetaX and Dynamia AI have enabled three distinct deployment paths to accommodate different scaling needs. Users can select an optimized baseline configuration for single-card operations, an optimized baseline for eight-card clusters, or a Prefill/Decode separation architecture for specialized workloads. This flexibility allows engineers to match the hardware to their specific latency and throughput requirements without rebuilding the inference pipeline from scratch.
The official inclusion of the Xi Cloud C Series in the llm-d accelerator list confirms that the hardware meets the technical standards for cloud-native distribution. This milestone validates the partnership between MetaX and Dynamia AI and establishes a reference point for future domestic GPU integrations. The card is now ready for immediate deployment in environments utilizing the llm-d framework.
Discussion
0 comments
Log in to join the thread with a thoughtful take, question, or correction.