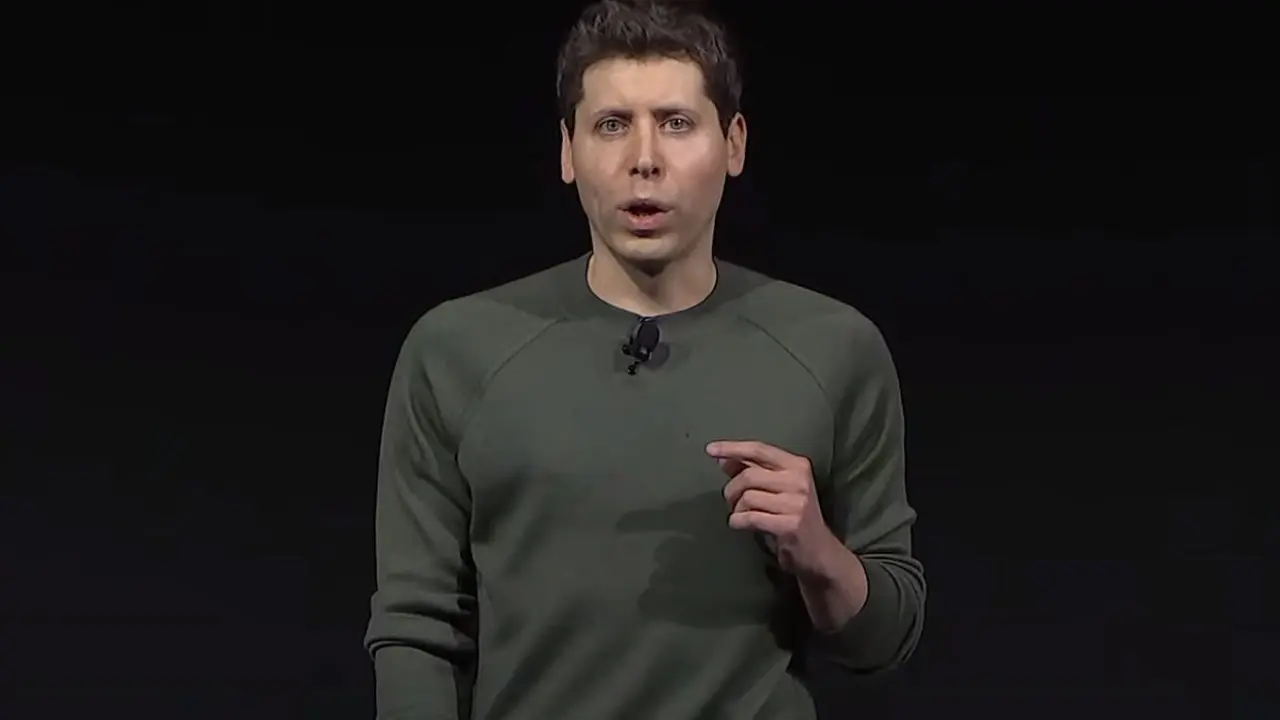
OpenAI's CEO Sam Altman retracts his claims about system memory that raised some eyebrows in the tech world. This is significant because it puts the right information about AI development requirements in the public. For people who were using previous comments as reference for their build, this correction serves as a new baseline to use.
OpenAI CEO clarifies misleading comments on system memory
In particular, the main focus of the update is Altman's recent statement about the RAM which is "terrible" and taken out of context. Essentially, this is a retraction of technical specs commentary made before. So instead of allowing this misinformation to continue, the company is directly trying to clear up the confusion.
To be more specific, Altman specifically addressed how he worded the original statement about memory constraints. He admits that it was a poor wording and does not properly reflect the technical aspects. The focus here is not to provide new hardware information but to correct the accuracy of the claim.
This editorial correction really shows just how much importance the hardware specs have in the AI industry. Misinterpretation of CEO's comments can easily affect buyer decisions and developer expectations. So the company is trying to set a straight narrative about their technical requirements.
wait so the ram comment was actually a mistake 😂
The context matters more than the raw number here. Altman is clarifying that the phrasing was poor but the underlying constraint discussion was valid for specific training runs. We need to look at the actual memory bandwidth requirements for the model size in question.
honestly i just hope this means the cloud instances are actually stable now and not just another hype cycle
What are the specific throughput numbers for the new architecture they are referencing? I need to see independent benchmark data before trusting any statement from leadership.
The article does not provide specific throughput numbers, only that Altman retracted the ‘terrible’ characterization. We likely need to wait for a technical white paper or a detailed blog post from the engineering team to get those hard metrics.
I just want to know if this affects the price of the service. I am tired of guessing what the compute costs will be next month.
Another retraction. The less said the better.