
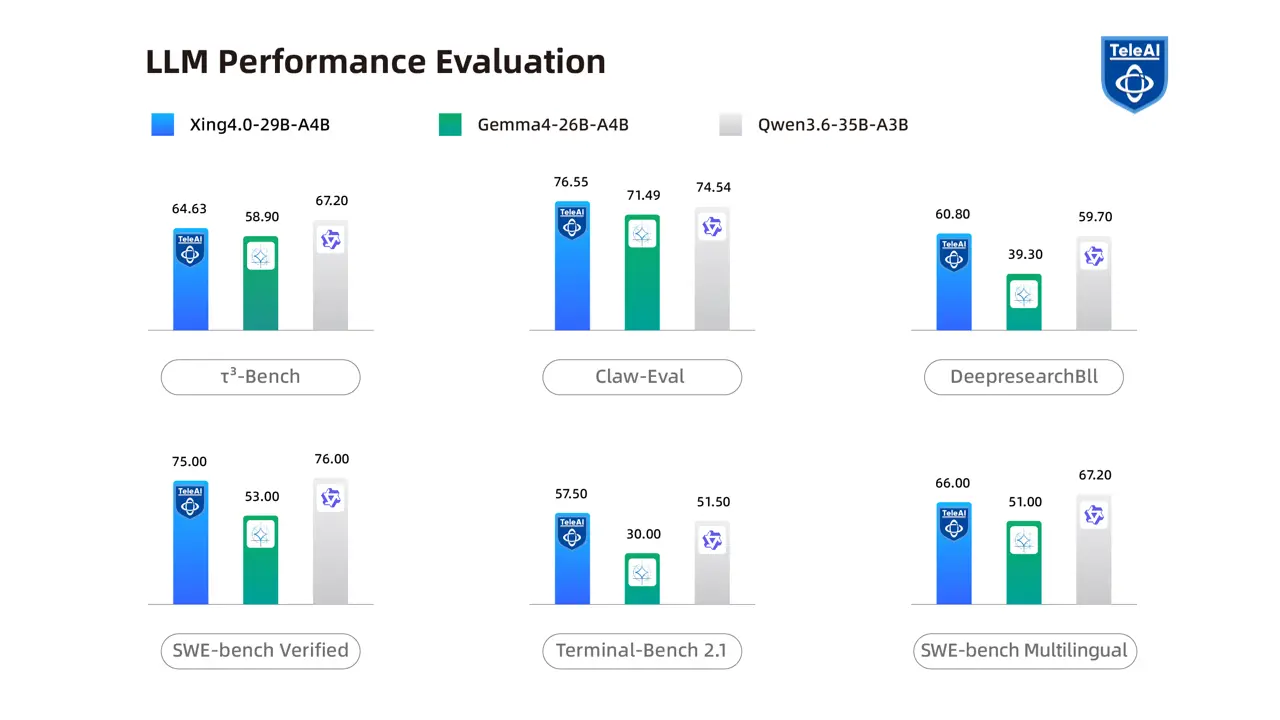
China Telecom AI Technology Co., Ltd. released the Xing4.0-29B-A4B model, which targets developers who need efficient code generation without heavy hardware costs. The release matters because it combines a large parameter count with a tiny active footprint, allowing complex tasks to run on modest consumer graphics cards. This approach lowers the barrier for teams that previously needed expensive server clusters to handle large language model workloads.
Lightweight code agent model ships with 4-bit quantization for consumer GPUs
The model uses a Mixture of Experts (MOE) architecture with 29 billion total parameters but only activates 4 billion during inference. This design choice significantly reduces the memory and compute resources required for each request. The system supports a native context window of 256,000 tokens, which developers can expand to 512,000 tokens for longer codebases.
- Model Architecture: MOE (Mixture of Experts)
- Total Parameters: 29B
- Active Parameters: 4B
- Context Window: 256K (expandable to 512K)
- SWE-bench Verified Score: 75.0
Performance benchmarks show the model scoring 75.0 on SWE-bench Verified and 57.5 on Terminal-Bench 2.1. These results exceed competitors of the same size and place the model third in SuperCLUE Agent capability with a score of 93.52. MetaX announced that its XiYun C series GPU completed Day 0 adaptation for the model using its self-developed MXMACA software stack, achieving 'adaptation upon launch'.
4-bit quantization reduces the VRAM requirement to just 15GB, which allows local execution on consumer GPUs like the RTX 3090 or 4090. The MXMACA software stack supports PyTorch 2.8 with 2410 GPU operators and works with over 40 AI frameworks. This compatibility reduces traditional model adaptation cycles from weeks to hours. We looked at Moore Threads MTT S5000 GPU Runs earlier while tracking China telecom ai technology co., ltd. launches.
The release confirms that lightweight code agents can now operate efficiently on accessible hardware. The combination of MOE architecture and aggressive quantization provides a practical path for local AI deployment. Developers can now run complex coding tasks without relying on cloud infrastructure.
Discussion
0 comments
Log in to join the thread with a thoughtful take, question, or correction.